AI writes code faster but teams ship no faster
Faros AI telemetry on 22,000 developers shows teams with high AI adoption complete 33.7% more tasks, yet deploy 11.7% less often each week while median review time grows about five times. DILR.ai fixes that review and verification stage, so faster coding turns into faster delivery.
High against low AI adoption, 2026
- WriteTasks completed per developer+33.7%
- ReviewMedian review timeabout 5x
- ShipDeployments per week11.7% fewer
- RunIncidents per pull request+242.7%
Does AI make developers faster in 2026?
Developers finish more tasks with AI but their teams ship less often
Faros AI compares teams with high and low AI adoption inside the same companies. Output rises. Review load, bugs and incidents rise faster.
Teams with high AI adoption compared with low adoption, 22,000 developers in 4,000 teams, two years of telemetry.
- Tasks completed per developer33.7% higher
- Epics completed66.2% higher
- Pull request merge rate16.2% higher
- Pull request size51% higher
- Bugs per developer54% higher
- Incidents per pull request242.7% higher
- Monthly incidents57.9% higher
- Deployments per week11.7% lower
Off this scale: median review time rose about 5x and code churn rose 861%.
Teams with high AI adoption compared with low adoption, over 10,000 developers in 1,255 teams.
- Tasks completed21% higher
- Pull requests merged98% higher
- Pull request size154% higher
- Pull request review time91% higher
- Bugs per developer9% higher
Faros found no significant link between AI adoption and company-level delivery metrics.
Sources: Faros AI, The Acceleration Whiplash (2026) and Faros AI, The AI Productivity Paradox (July 2025). Faros sells engineering analytics, and its figures show correlation within its customers' telemetry, not cause.
Do developers feel faster with AI than they really are?
Developers felt 20% faster in a trial that measured them 19% slower
METR timed experienced open-source developers on their own repositories, with AI allowed or not at random. How fast people feel is a poor guide.
- What developers expected before the trial24% faster
- What developers believed afterwards20% faster
- Measured in early 2025, 16 developers19% slower (range 2% slower to 39% slower)
- Measured in late 2025, returning developers18% faster (range 38% faster to 9% slower)
- Measured in late 2025, new developers4% faster (range 15% faster to 9% slower)
Early 2025: 16 developers, 246 tasks, METR, early-2025 developer study (July 2025). Late 2025: 57 developers, 800+ tasks, METR, experiment design update (February 2026). METR calls the late-2025 figures an unreliable signal that probably understates the speedup, because developers who would not work without AI declined to take part. Ranges are METR's confidence intervals.
Why does AI-generated code slow down code review?
Reviewers check more code from tools most developers do not fully trust
The 2025 Stack Overflow survey asked developers how AI tools behave in practice. Their answers describe a review problem, not a typing problem.
- 66%
say their biggest frustration is AI answers that are almost right, but not quite
- 45%
say debugging AI-generated code takes more time
- 46%
distrust the accuracy of AI tools, against 33% who trust it
Stack Overflow Developer Survey 2025, AI section. More than 31,000 developers answered each question, and 84% use or plan to use AI tools.
What does the DORA 2025 report say about AI?
DORA found that AI amplifies the team you already have
AI adoption was linked to higher delivery throughput and lower delivery stability. Strong teams get stronger, and weak review gets weaker.
- 90%of technology professionals use AI at work
- 80%+believe AI has increased their productivity
- 30%have little or no trust in code generated by AI
How do you fix the AI code review bottleneck?
Fix the review stage before you add more AI coding
More code into an unchanged review stage makes a longer queue. These four changes move the constraint.
Automate the checks a reviewer should not do by hand
Formatting, obvious defects, missing tests and convention drift are rules, not judgement. Every one a machine catches gives a reviewer time back for design and correctness.
Gate every merge with tests that score the change
An evaluation suite that runs on every change says whether it made the system better or worse, so speed stops costing stability.
Cap the size of what arrives for review
Faros measured pull requests 51% larger on high-adoption teams in 2026 and 154% larger in 2025. Two small changes are reviewed faster and better than one large one.
Report delivery for the team, not output per developer
Tasks and pull requests per developer rose in every telemetry study on this page while delivery did not. A dashboard of individual output will show a win your customers never feel.
How should you measure AI developer productivity?
Measure delivery for the whole team instead of output per developer
The left column rises with AI whether or not anything ships. The right column is what customers notice.
| Looks like progress | What your customers feel |
|---|---|
| Tasks closed per developer | Deployment frequencyHow often a change reaches users |
| Pull requests merged | Lead time for changesFrom commit to running in production |
| Lines of AI code accepted | Change failure rateShare of deployments that cause a failure |
| AI tool usage and acceptance rate | Failed deployment recovery timeHow fast a failed change is put right |
How do you prove work done by an AI agent is finished?
Cognibl will not close a task until proof of the work is attached
Cognibl is our work management product. People and AI agents share one board, and the same proof rule applies to both.
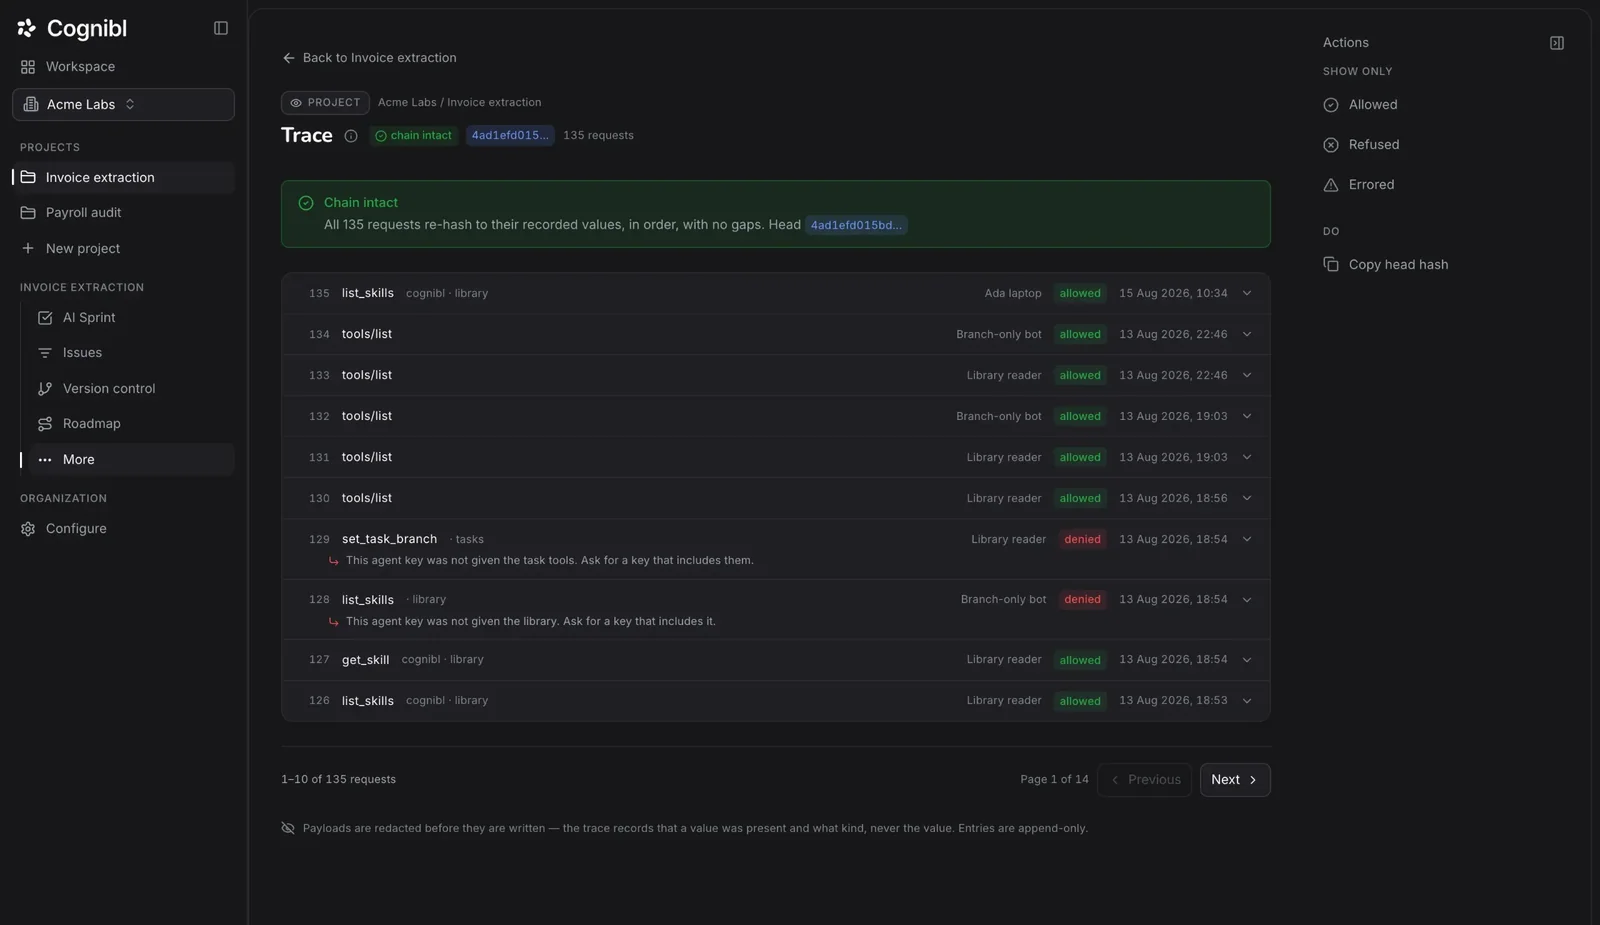
The proof rule
- Task assignedTo a person or an agent, on the same board
- Work in progressSame statuses for people and agents
- Proof version attachedRun CSV, artefacts, screenshots, hashes
- DoneThe move is accepted
Without a proof version, the database refuses the move to done, for people and agents alike.
Why it matters for AI-written code
An agent's task closes only with its run evidence attached, and every request its key makes is recorded. Review starts from proof instead of from a claim that the work is done.
Cognibl is free for one person and $5 per seat a month for teams.
Who can help fix AI developer productivity?
Our AI consulting fixes the review stage in three engagements
Start with the diagnostic if you do not yet know where delivery stalls. Start with the Execution Office if you already do.
4 to 6 weeks
AI Placement Diagnostic
Measures your delivery baseline and finds where AI changes it, so you know whether review is really the constraint.
How the Placement Diagnostic works6 to 10 weeks
AI Operating Model
Sets who owns AI-written code, how it is reviewed and what an agent is allowed to merge.
How the Operating Model works12 months or more
AI Execution Office
Embeds with your engineers to automate review checks, add merge gates and hand the result to a named owner.
How the Execution Office works
Does AI make developers faster, according to Reddit?
We link the Reddit threads so you can read developers’ views yourself
We link the searches instead of quoting them, because a thread cannot be checked the way a study can.
Does AI actually make developers faster?
Reddit search: does ai make developers faster
Is AI-generated code slowing down code review?
Reddit search: ai generated code review takes longer
What did developers make of the METR study?
Reddit search: metr study ai developers slower
How do teams measure AI coding productivity?
Reddit search: measure ai coding productivity dora
What else do people ask?
Short answers to common questions about AI developer productivity
Short answers with the source named in each. The figures are third-party research, not DILR client results.
- Individually it often does, but the gain rarely reaches delivery. Faros AI telemetry on 22,000 developers found teams with high AI adoption completed 33.7% more tasks, yet their median review time was about five times longer and they deployed 11.7% less often each week. Google DORA 2025 found AI linked to higher throughput and lower stability at the same time.
- Because review became the bottleneck. AI produces more and larger changes, and Faros measured pull requests 51% larger on high-adoption teams. Human review did not grow to match, so the queue absorbs the gain. The fix is to widen review and verification, which is the work of our AI Execution Office.
- In early 2025, yes. METR ran a randomised trial with 16 experienced open-source developers and found tasks took 19% longer with AI, while the developers believed they had been 20% faster. A larger late-2025 round estimated an 18% speedup for returning developers and 4% for new ones, but both ranges include no change and METR calls the new data an unreliable signal.
- Google DORA surveyed nearly 5,000 technology professionals. 90% use AI at work and more than 80% believe it raised their productivity, while 30% have little or no trust in AI-generated code. AI adoption was linked to higher delivery throughput and lower delivery stability. DORA concludes that AI amplifies what a team already has rather than fixing it.
- Measure the team, not the individual. Tasks and pull requests per developer rise with AI even when nothing ships sooner. Track deployment frequency, lead time for changes, change failure rate and failed deployment recovery time, the four DORA delivery measures, before and after AI is introduced. Our Placement Diagnostic sets that baseline first.
- Automate the checks a reviewer should not be doing by hand, gate every merge with tests that score the change, cap the size of pull requests, and report delivery at team level. Work done by AI agents should only close with proof attached, which is the rule Cognibl enforces for people and agents alike.
How do I get started?
Book a free consultation to find where your delivery stops
In 30 minutes we look at where your changes queue and what that costs you. You leave knowing whether review is the constraint, whether or not you work with us.